Deep dives from our engineering team
Practical guides on React, Node.js, DevOps, AI, and building production software. Written by developers who ship daily.
- Articles
- 607+
- Readers/mo
- 500+
- Topics
- 25
Found 37 articles in Hardware
Hardware11 min read
Optimizing GPU Memory for LLM Inference: Drive Cost & Performance
For production LLM inference, GPU memory (VRAM) and bandwidth are the ultimate bottlenecks, directly impacting throughput and cost. This guide dives deep into selecting and optimizing hardware, from local development to cloud deployments, ensuring your AI applications run efficiently.
Hardware10 min read
Choosing the Best Edge AI Hardware for Real-World Deployments
On-device intelligence is transforming industries, but selecting the right edge AI hardware is critical for performance, cost, and power efficiency. This guide navigates the options, from NPUs to specialized GPUs, for robust real-world applications.

Hardware10 min read
Choosing the Right Desktop GPU for AI Development & Fine-Tuning
For engineers and ML practitioners, selecting the right desktop GPU for local AI development and fine-tuning is crucial for productivity and cost efficiency. We break down the VRAM, performance, and ecosystem considerations for consumer-grade GPUs, helping you build a powerful developer workstation.
Hardware11 min read
Cost-Effective LLM Inference Hardware: Build Your Own Local AI
Navigating the complex world of LLM inference hardware requires a keen eye on both performance and budget. This guide demystifies the options, helping developers and small teams build efficient local AI solutions without breaking the bank, balancing VRAM, power, and throughput for optimal cost-effectiveness.

Hardware11 min read
Budget AI Hardware: Powering Local LLM Inference & Fine-tuning
Democratizing AI means making powerful models accessible. This guide cuts through the noise, detailing cost-effective hardware solutions for running LLM inference and fine-tuning locally, moving beyond expensive cloud services for specific workloads. Learn which specs matter most and how to optimize your setup for performance and price.

Hardware11 min read
Optimize LLM Inference Hardware Costs for Scale
Navigating the complex landscape of LLM inference hardware requires a deep understanding of cost-per-token economics. This guide breaks down cloud vs. on-premise trade-offs, VRAM requirements, and strategic recommendations to minimize expenditure while maximizing performance for your AI applications.

Hardware11 min read
Choosing the Best GPU for AI Training: Enterprise Hardware Deep Dive
Selecting the right GPU for AI training is critical for enterprise success. With new architectures emerging, understanding the nuances of VRAM, interconnects, and scalable performance across NVIDIA H100, Blackwell, and AMD MI300X is paramount for efficient machine learning training infrastructure.

Hardware10 min read
AI Accelerator Comparison: Choosing Your Enterprise ML Hardware
Navigating the complex world of AI accelerators is crucial for modern enterprise ML. This guide offers an engineering perspective on NVIDIA, AMD, and custom chips, helping you make informed hardware decisions for training and inference at scale.

Hardware10 min read
Sizing Developer Workstation Hardware for AI & Complex Builds
Choosing the right hardware is critical for engineers tackling modern AI models and demanding software projects. This guide breaks down CPU, GPU, and memory considerations for optimal performance, balancing cost with capability for your daily development workstation.

Hardware9 min read
Unlock Speed: High-Performance Storage for Web Applications
In 2026, application performance hinges on more than just CPU and RAM. The right storage hardware can drastically reduce latency, accelerate data-intensive operations, and transform user experience. This guide dissects modern storage options, from ultra-fast NVMe to scalable object storage, to help engineers, founders, and ML practitioners make informed decisions for their web and AI applications.

Hardware11 min read
Optimizing AI Inference Hardware: On-Prem vs. Cloud Efficiency
Choosing the right AI inference hardware is critical for managing costs and achieving performance targets in today's LLM-driven applications. We break down the complex trade-offs between dedicated on-premise solutions and flexible cloud GPU services, offering practical guidance for engineers and founders.
Hardware8 min read
Powering AI: The Rise of ARM Servers for Efficiency & Scale
The landscape of AI infrastructure is rapidly evolving, with ARM servers emerging as a compelling alternative to traditional x86 architectures. For engineers and founders building AI-driven products, understanding the performance, efficiency, and cost advantages of ARM-based solutions is crucial for long-term scalability and profitability.

Hardware10 min read
Selecting the Right Edge AI Hardware for On-Device Inference
Deploying AI models directly on devices at the edge presents unique challenges, from power consumption to real-time processing. This guide dives deep into selecting the optimal edge AI hardware, ensuring your on-device AI solutions deliver performance and efficiency where it matters most, without relying solely on cloud infrastructure.
Hardware11 min read
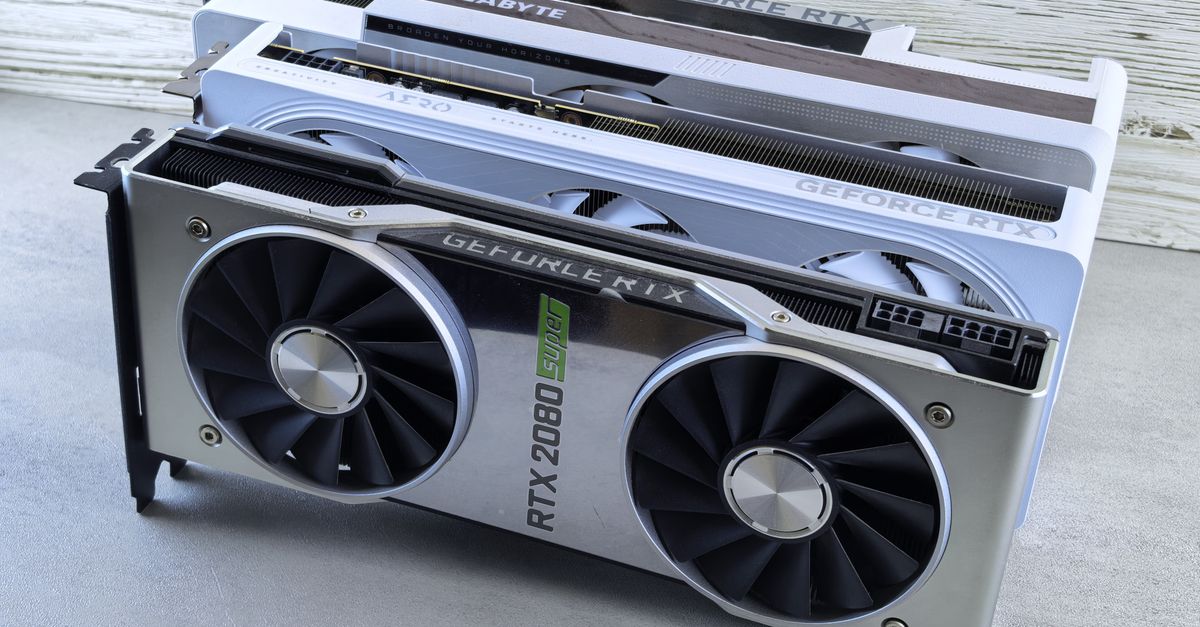
Choosing the Best GPU for LLM Inference: On-Prem, Cloud & Local Dev
Selecting the right GPU for LLM inference is a critical decision impacting both performance and cost. Whether you're deploying in the cloud, setting up on-premise, or developing locally, understanding VRAM, memory bandwidth, and architectural trade-offs is key to unlocking efficient AI applications.

Hardware10 min read
Best Hardware for AI Development: Powering Local Workloads
Choosing the right hardware for AI development is a critical decision that impacts performance, cost, and iteration speed. This guide dives deep into modern options, comparing Apple Silicon with high-end x86 workstations and dedicated GPUs for local AI inference, fine-tuning, and heavy development tasks.

Hardware7 min read
Apple Silicon vs x86 for Developers: Sizing Engineering Hardware
An in-depth engineering comparison of Apple Silicon vs x86 for developers, analyzing compilation speeds, Docker emulation, local LLM inference, and battery life.
Hardware4 min read
GPU VRAM for LLM Inference: Practical Sizing for Engineering Teams
Choosing the right hardware for LLM inference isn't just about raw speed. We break down VRAM requirements, cost-per-token trade-offs, and why memory bandwidth is the silent bottleneck in your AI stack.
Get engineering insights delivered to your inbox
One deep-dive every week. No spam. Unsubscribe anytime.
Join engineers who get our articles first.